Posts

Why You Should Learn Test Automation with Selenium IDE

Selenium IDE is one of the best tools for introducing testers to automated testing. Basically, it is a Firefox extension which was built by Shinya Kasatani. It provides an easy-to-use interface for creating an automated test with the help of capturing user actions what they perform and export as reusable scripts in many programming languages. Few people prefer only work with Firefox but now there is a compatible replacement offered by Katalon recorder for firefox and chromes which main aim to support all the features of the latest Selenium IDE. Benefits for a tester to learn test automation with Selenium IDE- It actually understands the test automation and its advantages. A proper understanding of what test automation is and avoids potential blunders. Follow working through common concepts such as locators, assertion, data-driven and many more. Creating the same tests in the popular framework and programming languages. All the steps are successfully tested wit...
What are the differences between Apache Spark and Apache Flink?

Firstly let us understand what Apache Spark is and what is Apache Flink? Apache Spark: It is an open source processing engine that provides an interface for programming entire cluster with implicit fault-tolerance and data parallelism. It was originally development at Berkeley 's AMP Lab , which was later donated to Apache Software Foundation. Apache Flink: Flink means agile. It is a data processing tool and process big data efficiently with high fault tolerance and low data latency on a large scale. It process streaming data in real time. Later it became the part of Apache Software Foundation. Similarities between Apache Spark and Apache Flink: Both projects are of Apache Software Foundation. Both are general purpose data processing platform. .Both come with in-built memory Both are used for big data scenarios. Both share a good performance. Both can run in standalone mode. Both have a wide field of applications. Although, they have ...

What Does Spark Replace Exactly?

Image
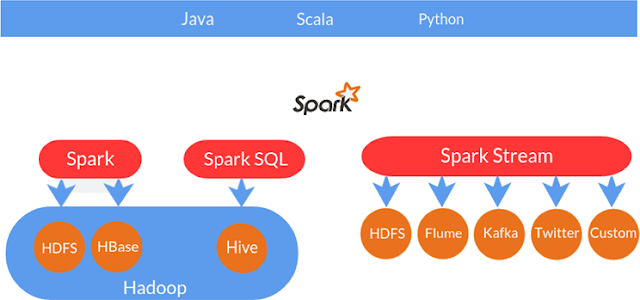
Spark and Storm are the two cousins companies that provide abstractions over Hadoop. Hadoop is a part of apache project; it is an open source distributed java based programming framework.   It supports the storage and programming of a large data set in distributed computing environment. It is sponsored by Apache software foundation. Spark and storm makes it easy to use this programming framework in some easy ways. Hadoop can take in lots of data and allows you to build a scalable system and do analytics on that data. If you successfully build it in Hadoop in right way, you can increase the capacity of your system by adding more servers. This helps you to spin your machines depending on the size of your load. Hadoop is practically flexible; you can use it in many different ways. Due to this it is also hard to work with. Hadoop consists of Hadoop common package. This package consists of necessary Java scripts and JAR files that are needed to start Hadoop. Every file sh...

What Is The Difference Between Apache Storm And Apache Spark?

Let us first discuss the similarities between Apache Storm and Apache Spark: Streaming jobs for both of these run until there is an unrecoverable failure or shutdown by user. Both of these are implemented in JVM based language. Scala and clojure are the two respective JVM languages. Differences between Apache Spark and Apache Storm are as follows: On the basis of definition: S.No Apache Spark Apache Storm 1 It is an open source processing engine that provides an interface for programming entire cluster with implicit fault-tolerance and data parallelism. Storm is simple and easy to reliably process the unbound streams of data. 2 It is a general purpose batch processing engine. It is a task parallel continuous engine 3 Defines its workflow in DAGs called topologies. Defines its workflow in style of MapReduce. 4 Executing applications run on own server processes. It uses Apach...